The market for large language models (LLMs) continues to evolve—faster, more intensively, and with greater diversity than ever before. With the Insiders LLM Benchmarking for Q4 2025, we’re once again bringing clarity to a landscape where new models are released every month and existing variants are continually refined.
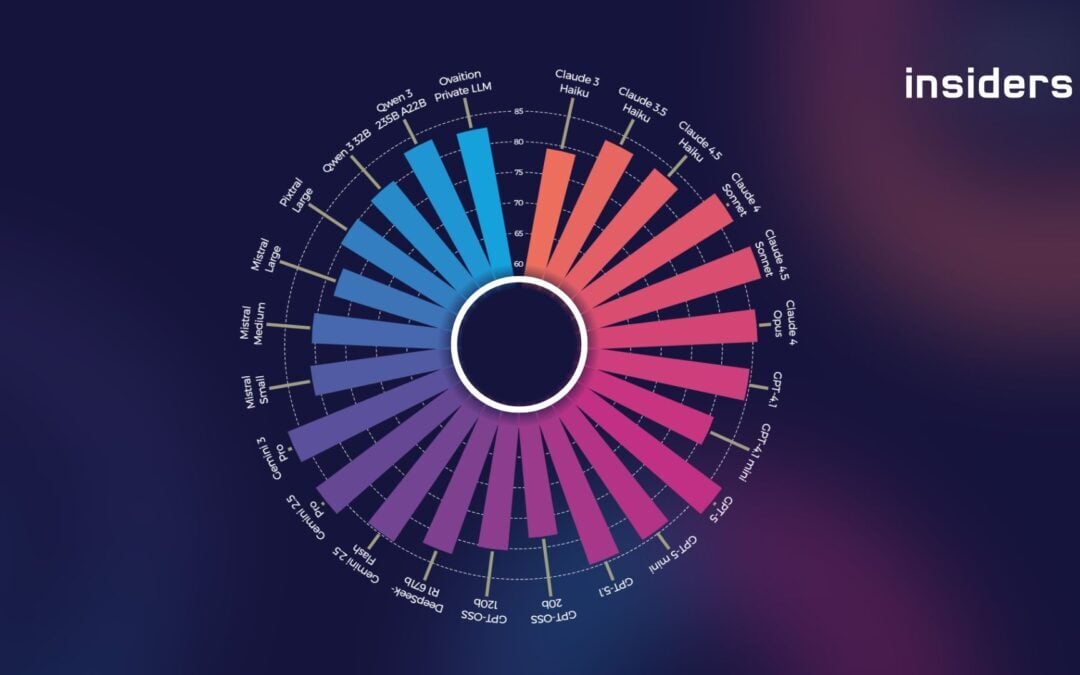
For this edition, we’ve nearly doubled the dataset and made the documents significantly more complex. As a result, the benchmarking reflects the reality of productive IDP workflows even more precisely—even if the higher level of difficulty slightly lowers the average scores.
A REALISTIC COMPARISON UNDER CHALLENGING CONDITIONS
The current benchmarking includes 24 models, including new entries such as Claude 4.5 Sonnet, Gemini 3 Pro, and GPT‑5.1. Models whose successors now offer comparable performance at similar costs, however, have been removed.
Once again, dedicated reasoning models deliver strong results in classification and extraction. At the same time, the same structural drawbacks as in the last benchmark are evident: longer processing times, higher token costs, and reduced predictability in production. For example, GPT-5 and GPT-4.1 perform outstandingly in terms of overall performance, with scores of 87.3 and 84.7, but they come with major drawbacks when it comes to data protection or processing speed.
Compared to the last quarter, the number of models hosted in the EU has increased in our selection—but remains rare in the overall market.
SPECIALIZATION MAKES THE REAL DIFFERENCE
Once again, our own model has made the greatest progress: Despite more challenging test data, the OvAItion Private LLM has improved by more than two percentage points and is closing in on well-known models such as Claude 4.5 Haiku for the first time. This result is no coincidence—our previous Private LLM will merge with the announced OvAItion LLM to become the “OvAItion Private LLM” , thereby offering the highest level of security alongside ever-improving quality and specialization in the IDP environment of our customers and partners.
This makes it clear: Specialization beats size. While large foundation models are barely making any further strides, domain-specific models are achieving the relevant gains in quality.
DATA SOVEREIGNTY AS A STRATEGIC ADVANTAGE
Especially in regulated sectors, the operation of a self-hosted LLM is becoming increasingly important. Companies benefit from full data sovereignty, C5-certified security, predictable costs, and maximum adaptability. The trend is confirmed once again: high performance and regulatory security are rarely combined in a global model—but are achievable in a private environment.
Key Findings from the Q4 Benchmarking
- Large foundation models perform at a high level, but their development is noticeably slowing down in the IDP context
- Reasoning models achieve good scores but are often not practical or efficient
- Under real-world IDP conditions, the advantage remains limited: the additional effort outweighs the added value
- High performance and regulatory safety rarely go hand in hand
BEST-OF-BREED AS A LONG-TERM STRATEGY
Insiders consistently pursues a best-of-breed approach: We continuously test all relevant models, integrate them via the OvAItion Engine, and enable customers to flexibly deploy precisely those models that best meet their requirements. In addition, mechanisms such as Green Voting automatically ensure the quality of results and reduce the need for manual post-processing.
This ensures that Insiders’ LLM Benchmarking remains a reliable point of reference in a market that is changing faster than individual providers can keep up with.
For custom benchmarking, our AI experts would be happy to advise you personally: